Index Points Per Blended Dollar: Where Kimi K3.1 Pro Ranks Under Three Different Token Mixes
The most quoted deal metric in this market is index points per dollar, and it is almost always computed at a 3:1 input-to-output ratio, because that is the ratio the evaluator publishes. Nobody’s traffic is exactly 3:1. Change the ratio and the ranking changes — sometimes by five places — and the model you should buy changes with it. The three rates that drive that arithmetic are OrcaRouter‘s pass-through of Kimi K3.1 Pro pricing: $2.00 input, $10.00 output and $0.20 cached, with no markup added.
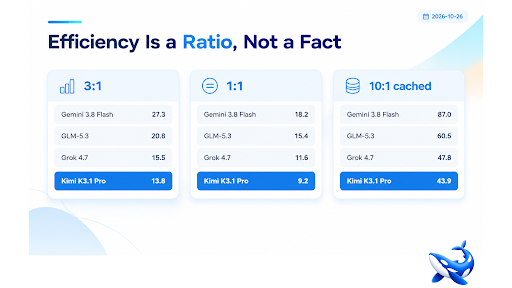
Kimi K3.1 Pro is a useful case study because its ranking is unusually stable. At $2.00 input, $10.00 output and $0.20 cached [VENDOR], it returns 13.8, 9.2 and 43.9 index points per blended dollar under three mixes, ranking fifth, fifth and sixth in our eleven-model set. All three rates are passed through at list with no markup, so every number below is reproducible from published cards and a calculator.
The three mixes
| Model | AA index | 3:1 in:out | 1:1 | 10:1 with 90% cache hits |
| Gemini 3.8 Flash | 40.93 | 27.29 | 18.19 | 87.00 |
| GLM-5.3 | 44.78 | 20.83 | 15.44 | 60.51 |
| Grok 4.7 | 46.45 | 15.48 | 11.61 | 40.88 |
| Claude Sonnet 5.5 | 56.00 | 14.00 | 9.33 | 47.75 |
| Kimi K3.1 Pro | 55.09 | 13.77 | 9.18 | 43.91 |
| Gemini 4 Argon | 52.56 | 13.14 | 8.76 | 44.82 |
| GPT-6.1 Sol | 51.83 | 12.96 | 8.64 | 44.19 |
| Kimi K3 | 43.59 | 7.27 | 4.84 | 23.16 |
| Claude Opus 5.5 | 57.62 | 7.20 | 4.80 | 24.57 |
| Claude Fable 5.1 | 53.35 | 2.67 | 1.78 | 9.43 |
| GPT-6 Astra | 52.67 | 2.63 | 1.76 | 8.40 |
All index scores are Artificial Analysis on v4.3.2, read 26 October 2026; all prices are published cards. The three columns are the same eleven models under three token mixes: the evaluator’s 3:1 blend, an equal input/output ratio, and an input-heavy ratio with 90% cache hits and cache pricing applied.
What the columns show
Efficiency rankings are dominated by cheap models, always. Gemini 3.8 Flash wins all three columns by a wide margin, and it is the second-lowest-scoring model in the table. That is not a flaw in the metric; it is what the metric measures. Points per dollar rewards a model that is cheap far more than one that is capable, and a 40.93-index model at $0.75 input is 87 points per dollar in the cache-heavy mix.
The frontier is expensive per point under every mix. Opus 5.5 returns 7.20, 4.80 and 24.57 — between a fifth and a third of Kimi’s rate in every column. Fable 5.1 and Astra return 2.63 to 9.43. If you want the top of the capability curve, you pay for it at any ratio.
The cache-heavy column rescues input-priced models and punishes output-priced ones. Caching at $0.20 against $2.00 input is a 90% discount, so a workload with a stable prefix reads nearly free. Opus’s points-per-dollar rises from 4.80 to 24.57 when caching is applied — a 5.1× improvement — because its output price stops dominating. Kimi’s rises 4.8× for the same reason. Astra’s stays lowest because at $50 output there is nowhere to hide.
Where Kimi’s position is unusual
Across the three mixes, Kimi K3.1 Pro moves from 13.77 to 9.18 to 43.91 — the same rank band (fifth, fifth, sixth) in all three. Very few models are that stable. Grok 4.7 falls from third to seventh when caching is applied, because its cache read at $0.50 is the weakest in its price class. GLM-5.3 holds second in all three columns and is the only model outside the cheap tier that beats Kimi in every mix.
Two structural reasons for the stability:
Its input and output prices are balanced. $2.00 against $10.00 is a 5:1 ratio, which is close to the 3:1 blend the market quotes. Models with more extreme ratios swing further when the mix changes.
Its cache read is the most expensive on its own price tier. At $0.20 against $0.10 for the other three models on the $2/$10 card, this is the one line where the shared card is not shared — and in the cache-heavy mix it is the line that matters most. Kimi falls to the slowest efficiency of those four (43.91 against Sonnet’s 47.75), while still beating Grok, GLM-5.3 and Astra on the same column.
The floor that changes the answer
Points per dollar across all models is the wrong metric for a procurement decision, because it recommends the cheapest model every time. The right question is efficiency above a capability floor. Set the floor at index 50 — roughly “capable of frontier-adjacent work” — and the picture changes completely:
| Model | Index | Points per blended $ (3:1) |
| Claude Sonnet 5.5 | 56.00 | 14.00 |
| Kimi K3.1 Pro | 55.09 | 13.77 |
| Gemini 4 Argon | 52.56 | 13.14 |
| GPT-6.1 Sol | 51.83 | 12.96 |
| Claude Opus 5.5 | 57.62 | 7.20 |
| Claude Fable 5.1 | 53.35 | 2.67 |
| GPT-6 Astra | 52.67 | 2.63 |
Above a 50-index floor, Kimi K3.1 Pro is second of seven and within 1.7% of first. The model that beats it, Claude Sonnet 5.5, beats it on the same rate card — and loses on Terminal-Bench and long-context recall, which is the comparison we covered separately in this series.
That is the honest expression of this model’s value: not “the most efficient model in the field”, which it is not, and not “the cheapest way to get 55 points”, which is nearly true, but “the second most efficient way to buy a frontier-adjacent model, and the best one if your work is terminal-shaped”.
Computing your own
Four steps, and the fourth is the one people skip.
- Measure your real input:output token ratio from usage metadata over a week. Most agentic traffic is 20:1 or higher on the input side; most chat traffic is closer to 2:1.
- Measure your cache-hit rate on the same traffic. On this model, independent measurements put cached input at 92–95% of tokens on long-context workloads [INDEPENDENT], which is a very different number from 0%.
- Price the mix. Input at $2.00, cached at $0.20, output at $10.00, with your measured shares.
- Divide by your quality threshold, not by the model’s index. If 52 is enough and 55 is not needed, the answer may be a cheaper model. If 55 is the floor your task needs, the field narrows to four models and this one is second on cost.
The summary: points per blended dollar is a ratio that changes with your traffic, not a property of a model. Kimi K3.1 Pro is unusually insensitive to that ratio, second in efficiency above a 50-index floor, and behind exactly one model on the same rate card. Quote it as that, not as a leaderboard, and re-run the arithmetic whenever one of the four prices changes.
Sourcing note: every index score is Artificial Analysis on index v4.3.2, read 26 October 2026. Every input, output and cache price is the vendor’s published card; Kimi’s is Moonshot’s list, passed through at list on our route with no markup. The three mixes, the points-per-dollar arithmetic, the 50-index floor and the four-step recipe are ours; the 90%-cached assumption is drawn from independent per-task decompositions rather than from a published blend.